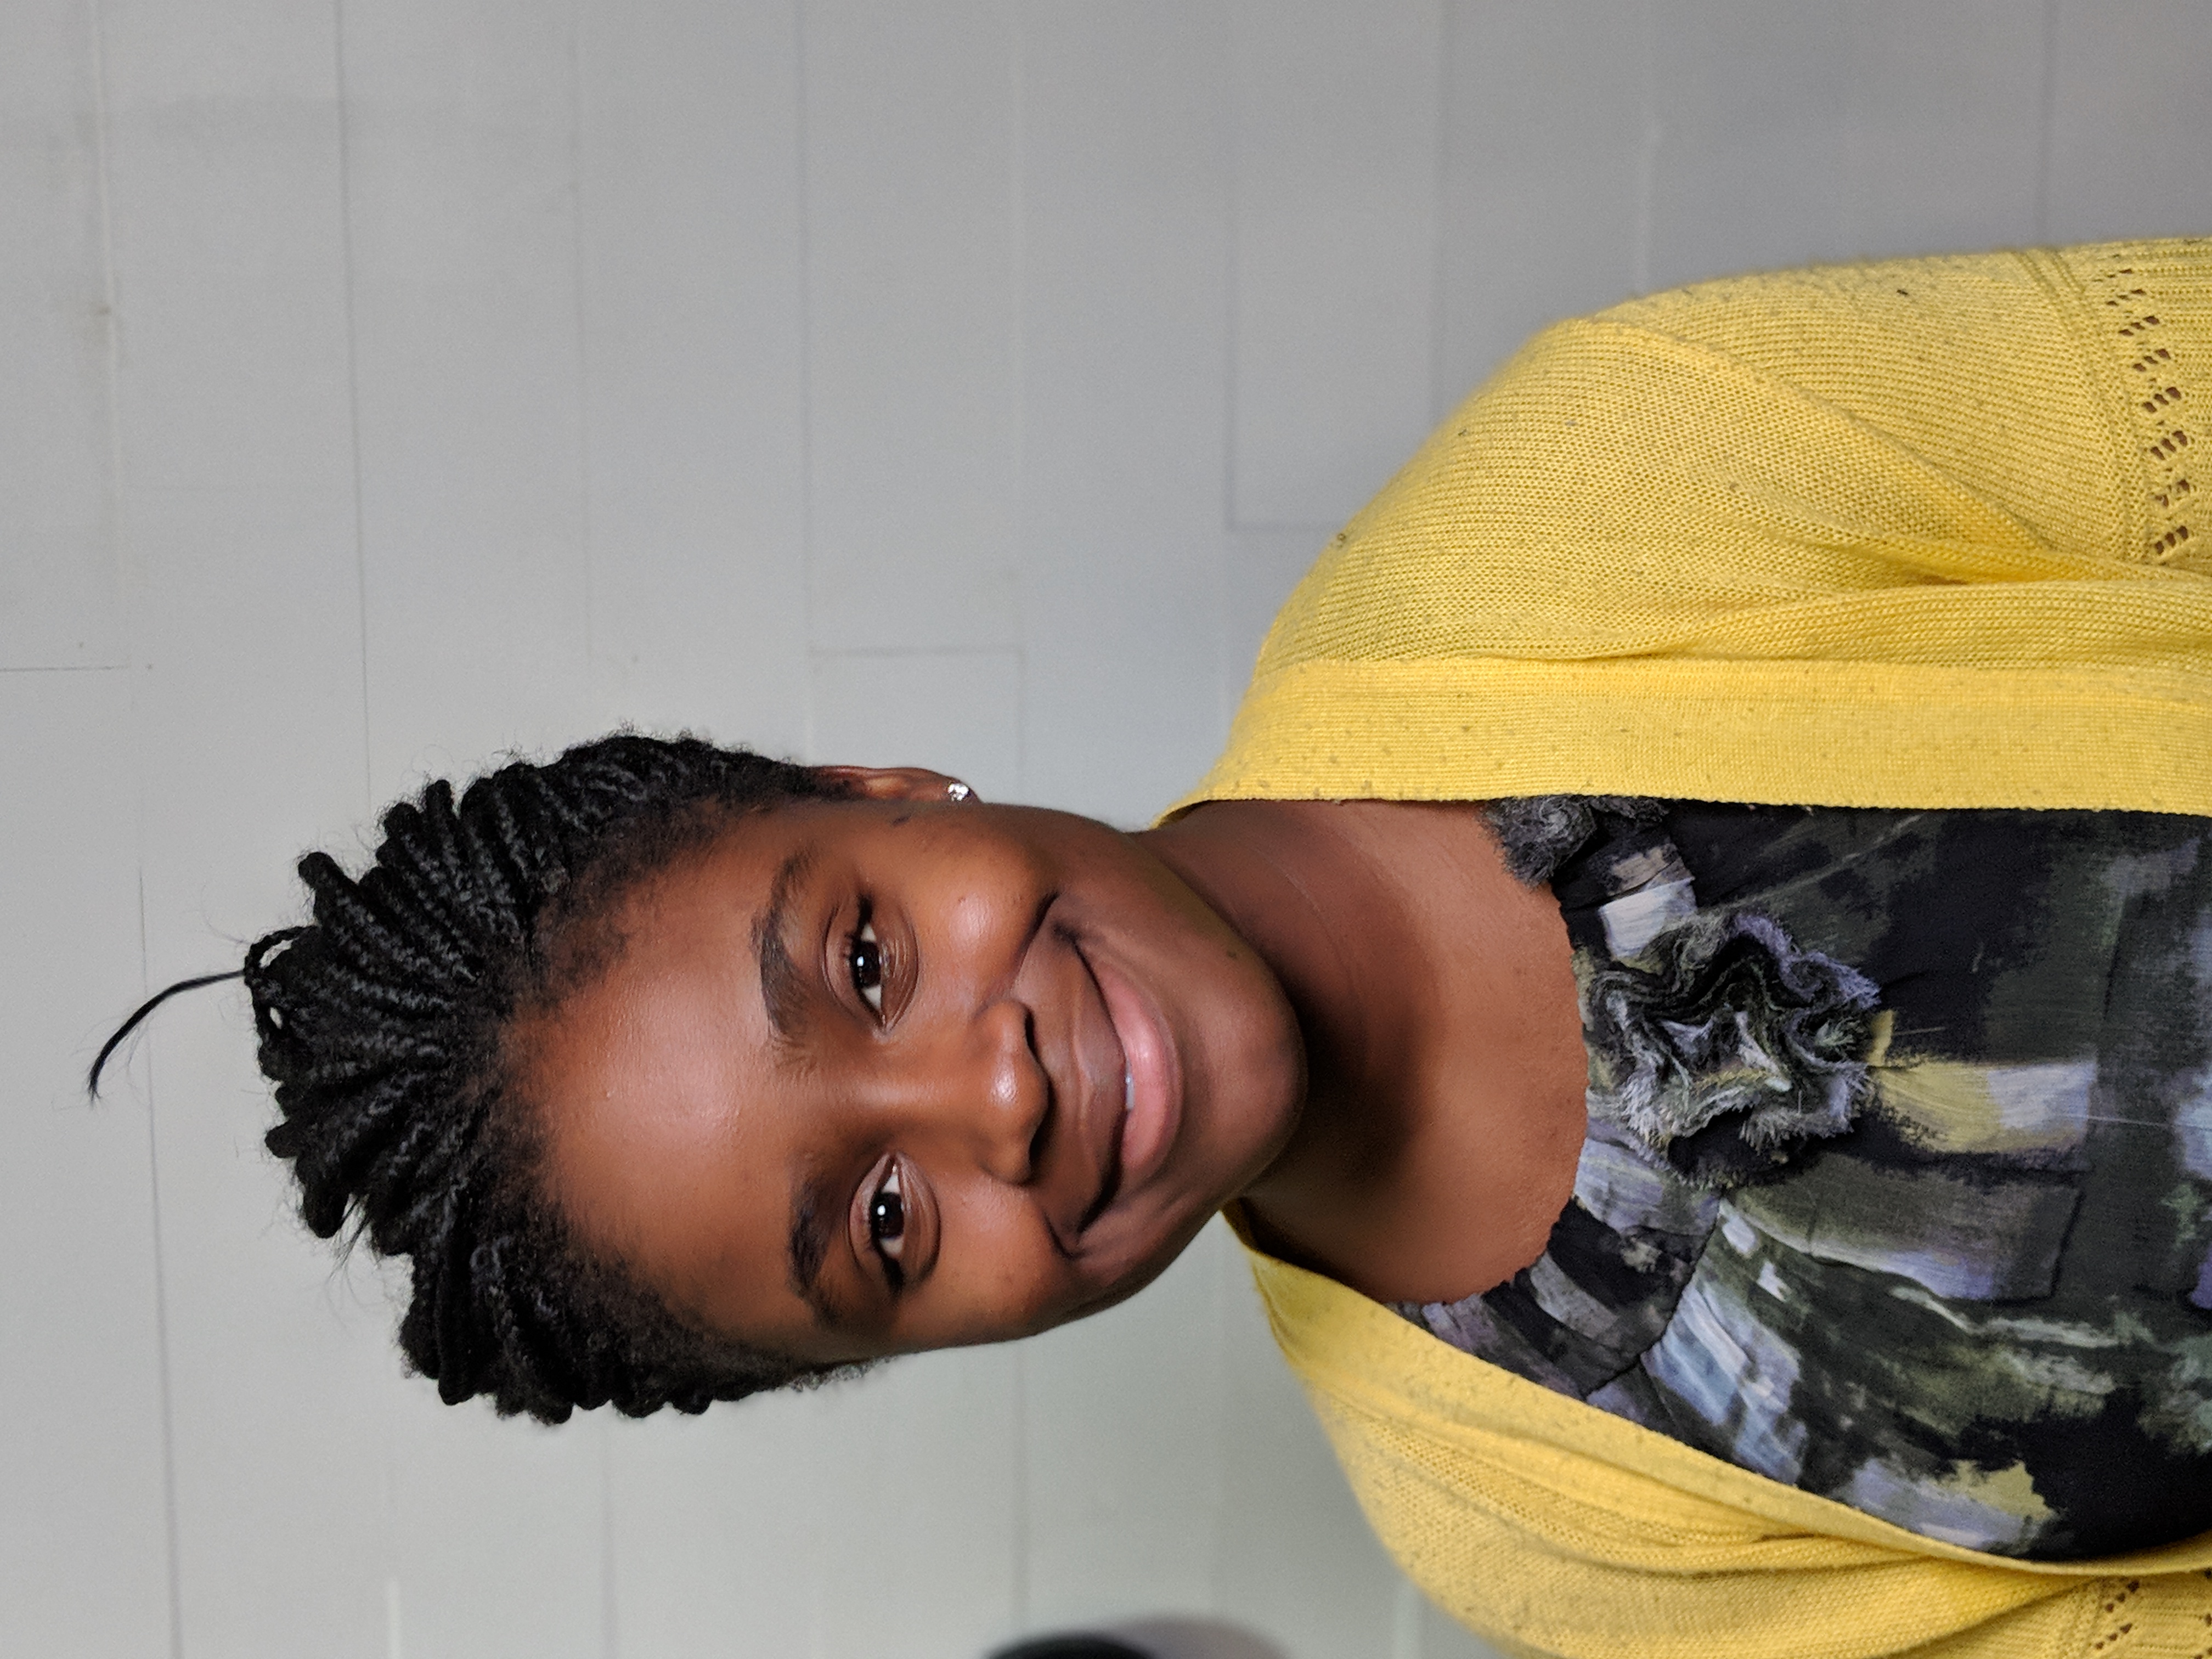
Deborah Raji works on how AI systems are audited in practice and why audits so often fail to change anything. She co-authored Actionable Auditing, the follow-up study on how commercial face-recognition products responded to public audit findings, and writes on the gap between claimed and actual model functionality.
Websiterajiinio.github.io
#AI auditing#accountability#AI ethics
Key arguments & positions
Argues an audit only matters if something changes afterwards — and documents how often nothing does.
Holds that many deployed systems fail on their own terms before bias is even discussed: they simply do not work as claimed.
Argues audit authority needs to sit with regulators and affected communities, not only with the vendor.
Accomplishments
Co-author of "Actionable Auditing" (2019), which tracked how commercial face-recognition vendors responded to public audit findings.
Worked with the Algorithmic Justice League on face-recognition audits, and later at Mozilla and UC Berkeley on AI accountability.
Named to the TIME100 AI list for her auditing work.
Raji and colleagues examine the ethics of the audits themselves: who is photographed, who consented, and what an auditor owes the people in the test set.
From the site: Although essential to revealing biased performance, well intentioned attempts at algorithmic auditing can have effects that may harm the very populations these measures are meant to protect. This concern is even more salient while auditing biometric systems such as facial recognition, where the data is sensitive and t…
Why I recommend it: A rare paper about the ethics of doing ethics work. Free on arXiv.
Raji and colleagues argue many deployed AI systems fail on their own stated terms — they simply do not work — and that this belongs in the harm conversation alongside bias.
From the site: Deployed AI systems often do not work. They can be constructed haphazardly, deployed indiscriminately, and promoted deceptively. However, despite this reality, scholars, the press, and policymakers pay too little attention to functionality. This leads to technical and policy solutions focused on "ethical" or value-ali…
Why I recommend it: The first question is not "is it fair" but "does it work at all". Free in full on arXiv.
Raji and co-authors show that benchmarks claiming to measure general ability measure something much narrower, and that the gap is how overclaiming happens.
From the site: There is a tendency across different subfields in AI to valorize a small collection of influential benchmarks. These benchmarks operate as stand-ins for a range of anointed common problems that are frequently framed as foundational milestones on the path towards flexible and generalizable AI systems. State-of-the-art…
Why I recommend it: Read this before you trust a benchmark chart in a launch post. Free on arXiv.
Deborah Raji and co-authors set out a practical, stage-by-stage internal audit process for AI systems, from scoping through to post-deployment review.
From the site: Rising concern for the societal implications of artificial intelligence systems has inspired a wave of academic and journalistic literature in which deployed systems are audited for harm by investigators from outside the organizations deploying the algorithms. However, it remains challenging for practitioners to ident…
Why I recommend it: The closest thing to a step-by-step audit template you can use inside an organization. Free on arXiv.